Submitted to ICASSP 2027 · submission
Projected Audio Tokens Gain Retrieval and Lose Grounded Generation in Multimodal LLMs
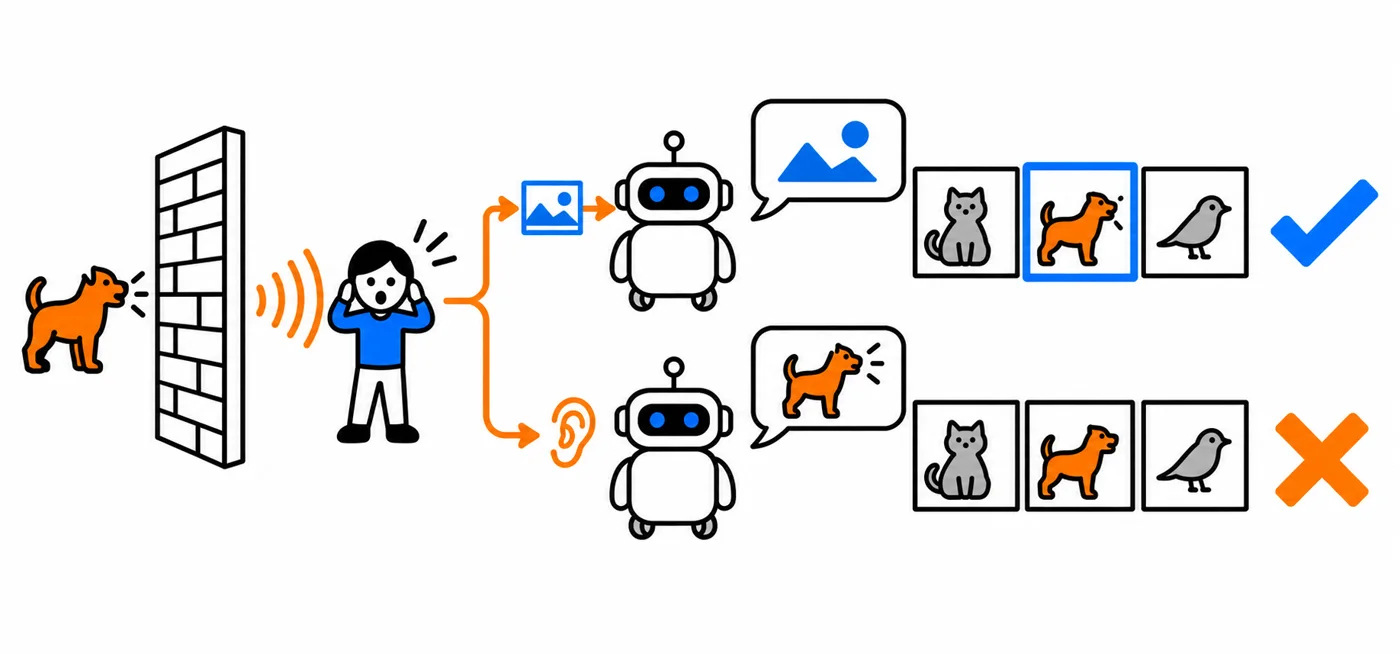
SoundCLIP: audio tokens projected into a LLaVA-style multimodal LLM gain retrieval and lose grounded generation; built on the AVE-2 dataset.
My part. Explored SoundCLIP and WhisperCLIP-style token-substitution methods that exposed a practical retrieval-versus-generation trade-off.
SoundCLIP: audio tokens projected into a LLaVA-style multimodal LLM gain retrieval and lose grounded generation; built on the AVE-2 dataset.
Under review. Listed as a submission; nothing here claims acceptance.