EUSIPCO 2025
Quality Over Quantity? LLM-Based Curation for a Data-Efficient Audio-Video Foundation Model
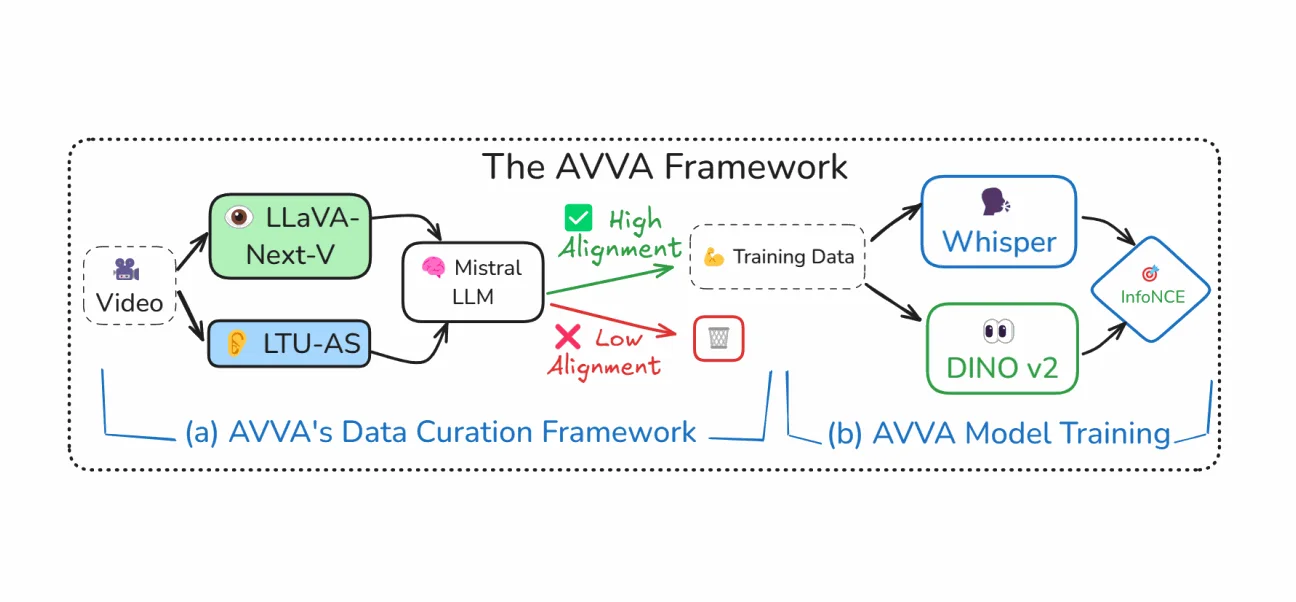
Data-efficient audio-video foundation modeling with LLM-based curation (AVVA); the AVE-2 dataset of 570,138 clips.
My part. Built large-scale audiovisual learning pipelines for dataset curation, cross-modal retrieval and multimodal LLM integration; engineered a weak-supervision stack combining LTU-AS, LLaVA-NeXT and Mistral 7B.
Data-efficient audio-video foundation modeling with LLM-based curation (AVVA); the AVE-2 dataset of 570,138 clips.